Monday, May 22, 2024
Chassis Fatigue Limit Test Basics: What Results Actually Matter in Vehicle Validation
by
Published
Views:
In vehicle validation, a chassis fatigue limit test is more than a pass/fail exercise—it reveals how a structure behaves under repeated loads, design margins, and real-world durability risks. For technical evaluators, the results that actually matter are not just cycle counts, but load thresholds, crack initiation patterns, stiffness change, and failure location, all of which shape reliable engineering decisions.
For engineering teams, sourcing managers, and benchmarking specialists working across automotive, off-highway equipment, and adjacent industrial platforms, the value of a chassis fatigue limit test lies in decision quality. A test that reaches 1 million cycles without context can still hide weak weld toes, load path instability, or excessive compliance. In a cross-sector environment where EV platforms, smart utility vehicles, and heavy-duty mobility systems share suppliers and materials, technical evaluators need results that support design release, supplier comparison, and lifecycle risk control.
This is where disciplined interpretation matters. At Global Industrial Matrix (GIM), chassis durability data is most useful when it can be benchmarked against standards, manufacturing variation, and real operating duty. For buyers and validation teams, the objective is not simply to ask whether the test passed, but whether the result provides enough resolution to predict field durability, warranty exposure, and platform robustness across 3 to 5 years of product evolution.
Why a Chassis Fatigue Limit Test Matters Beyond Pass/Fail
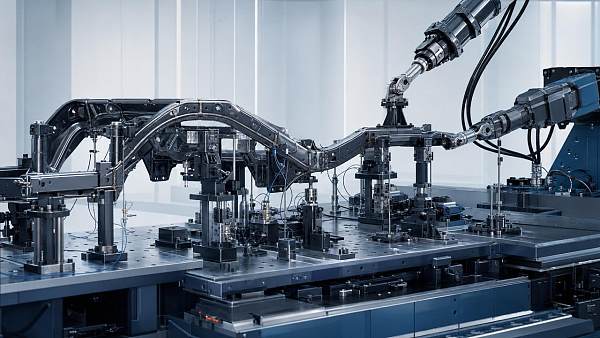
A chassis fatigue limit test evaluates how a frame, subframe, or structural assembly responds to repeated cyclic loading at defined amplitudes and frequencies. Depending on the application, the test may run at 2 Hz to 20 Hz, cover 100,000 to more than 2,000,000 cycles, and simulate vertical bending, torsion, braking loads, or multi-axis road inputs. For technical evaluators, the test becomes a validation gateway for design maturity, manufacturing consistency, and expected field survival.
The reason this matters across the broader industrial landscape is simple: chassis systems no longer operate in isolation. Battery mass in EVs, sensor brackets in autonomous vehicles, suspension packaging, and ESG-driven lightweighting all change load paths. A small increase of 8% to 12% in local mass or bracket stiffness can shift fatigue hotspots to areas that were previously non-critical. That means the chassis fatigue limit test must be read as a system-level indicator, not a stand-alone structural score.
What the test is actually trying to reveal
At a practical level, the test helps answer four engineering questions. First, what is the fatigue threshold under repeated service-like loading? Second, where does damage begin? Third, how fast does damage propagate after initiation? Fourth, how much stiffness is lost before final failure? These four outputs often influence release timing more than the raw cycle count.
- Load threshold at which no critical crack is observed within a target cycle window
- Crack initiation location, such as weld root, heat-affected zone, bracket corner, or hole edge
- Progressive stiffness loss, often tracked at intervals such as every 50,000 or 100,000 cycles
- Failure mode, including brittle fracture, weld separation, local buckling, or fastener-related damage
Why cycle count alone is incomplete
A reported result of 800,000 cycles to failure sounds useful, but it is often insufficient for procurement or validation decisions. Was the load amplitude 70% of peak service load or 120%? Did failure occur after crack growth over 200,000 cycles, or did the structure lose 15% stiffness early and continue in a degraded state? Did the test article represent nominal production build, prototype weld quality, or a hand-reworked sample? Without that context, comparisons between suppliers or programs become unreliable.
This is especially important when benchmarking across mixed manufacturing ecosystems. Two chassis assemblies may both survive 1.2 million cycles, yet one may show crack initiation at 300,000 cycles with slow growth, while the other remains intact until 1 million cycles and then fails abruptly. Those are different risk profiles for service planning, inspection intervals, and design margin interpretation.
Which Results Actually Matter in Vehicle Validation
Technical evaluators should focus on a compact set of outputs that connect the chassis fatigue limit test to real product decisions. The most decision-relevant results usually fall into 6 categories: fatigue limit threshold, crack initiation timing, damage location, stiffness degradation, correlation to simulation, and repeatability between samples. If one of these is missing, the test may still be useful, but its value for sourcing or release control drops significantly.
1. Fatigue limit threshold
The fatigue limit threshold is the load level below which the structure can endure a defined number of cycles without critical failure. In many validation programs, engineers evaluate multiple amplitudes such as 60%, 75%, 90%, and 100% of the target service-equivalent load. The result is not only a number, but a usable boundary for design margin. A threshold that sits less than 10% above expected duty is usually a warning sign for heavy-use fleets or regional overload scenarios.
2. Crack initiation timing and pattern
When the first crack appears matters almost as much as when final failure occurs. If a crack starts at 150,000 cycles in a 1,000,000-cycle test, the structure may still finish the test, but the design may have poor damage tolerance. Evaluators should request inspection intervals, NDT checkpoints, or high-resolution image logs. Crack initiation patterns often reveal whether the weakness is linked to geometry, residual stress, weld execution, or fixture-induced loading distortion.
Common crack origins to monitor
- Weld toe transitions with sharp radius changes
- Bracket interfaces carrying secondary bending loads
- Pierced or laser-cut holes near bolted joints
- Cross-member connections with local stiffness mismatch
3. Stiffness change during the test
A stiffness reduction of 5% to 10% can indicate meaningful structural damage before visible fracture develops. This is one of the most underused outputs in a chassis fatigue limit test review. If displacement under constant load rises steadily every 100,000 cycles, the structure may be accumulating micro-damage in welded joints, bonded interfaces, or adjacent mounting points. For validation teams, stiffness trend data often provides earlier warning than end-of-test failure mode alone.
4. Failure location and load path relevance
A failure in a non-critical bracket is not equal to a failure at a primary rail-to-cross-member node. Technical evaluators should classify the failure location by structural significance, service detectability, and repair consequence. If the failing region is difficult to inspect in the field or directly influences steering, battery support, or suspension geometry, the risk multiplier is much higher even if the cycle count looks acceptable.
The table below shows which chassis fatigue limit test outputs tend to carry the most weight during validation reviews and supplier benchmarking.
The practical takeaway is that a strong chassis fatigue limit test report should enable trade-off decisions. It should help teams judge whether a design change is needed immediately, whether a supplier variation is acceptable, or whether the issue can be controlled through process capability and inspection frequency.
How to Interpret Test Data for Benchmarking and Procurement
In B2B technical evaluation, test data is only valuable if it is comparable. This is where benchmarking discipline matters. A chassis fatigue limit test run on one fixture, one weld condition, and one load definition cannot be compared directly with another unless the test setup, acceptance criteria, and instrumentation strategy are aligned. For procurement teams, poor comparability can lead to incorrect sourcing decisions, especially when cost differences are within 5% to 8% but durability exposure differs substantially.
Key comparability factors
- Load case definition: single-axis, biaxial, or multi-event sequence
- Sample build condition: prototype, pilot, or serial-production equivalent
- Instrumentation density: strain gauges, displacement channels, crack monitoring points
- Environmental conditions: ambient, thermal cycling, or corrosive preconditioning
- Failure criteria: visible crack, stiffness loss threshold, or complete structural separation
For example, a component tested at room temperature after no corrosion exposure may outperform the same part by 15% to 25% relative life compared with a salt-spray preconditioned sample. That difference can be critical for commercial vehicles, agricultural equipment, and utility fleets exposed to moisture, chemicals, and particulate contamination.
Questions technical evaluators should ask suppliers or labs
Before relying on any chassis fatigue limit test result, evaluators should request a minimum data package. This does not require confidential design disclosure, but it does require enough technical transparency to judge robustness and repeatability.
- How many samples were tested: 1, 3, or more than 5?
- What was the coefficient of variation in failure cycles or stiffness loss?
- Were welds made using representative production parameters?
- Was fixture compliance measured and compensated?
- Were strain results correlated to FEA within a tolerance such as ±10% or ±15%?
The following table provides a practical evaluation framework that technical teams can use during supplier review, program gate approval, or cross-platform benchmarking.
This framework helps separate attractive test summaries from decision-grade evidence. For multi-plant sourcing or Tier-1 quality assessment, that difference can determine whether a platform enters launch with controlled risk or with hidden durability exposure.
Common Misinterpretations and How to Avoid Them
One of the most common mistakes is treating the chassis fatigue limit test as a universal durability proof. In reality, the test is a targeted tool. If the load spectrum does not reflect curb strikes, torsional off-road inputs, battery pack inertia, or payload asymmetry, the result may be directionally useful but not fully representative. Evaluators should always ask what duty cases are excluded and whether that exclusion is acceptable for the intended market.
Misinterpretation 1: Surviving the test means the design is robust
A design can survive a target of 1 million cycles and still carry limited margin. If it passes with a small stiffness drift at nominal load but fails rapidly at 1.1 times the load, the reserve may be too low for abuse cases, operator variability, or future derivative models. This matters when one chassis architecture is expected to support 2 or 3 product variants with different mass distributions.
Misinterpretation 2: The first failure is always the most important
Not every initial crack deserves the same response. Some cracks are non-propagating within service life, while others are rapid-growth triggers. The correct interpretation depends on stress redistribution, detectability during maintenance, and whether the failure compromises a safety-critical path. A small crack in a secondary tab may be manageable; a similar crack at a suspension pickup point is not.
Misinterpretation 3: One good test equals supplier capability
A single successful sample does not prove manufacturing control. For welded chassis assemblies, process variation in heat input, penetration, gap, and fixturing can shift fatigue life significantly. In many industrial programs, the right question is not whether the best sample passed, but whether the average build with normal variation can meet the threshold consistently over 3 production lots or more.
Practical safeguards for evaluators
- Use at least 3 review layers: test setup, result quality, and production relevance
- Track both crack initiation and final failure, not just one endpoint
- Review stiffness change at regular intervals instead of only start and finish
- Require photo documentation and failure mapping for each sample
- Compare results with CAE and manufacturing process capability before release
Turning Test Results into Better Engineering and Sourcing Decisions
The best chassis fatigue limit test programs are decision-oriented from the start. They define the load cases, data checkpoints, and acceptance logic needed for release, redesign, or supplier nomination. For technical evaluators, this means linking test evidence to a clear action path: approve, monitor, redesign, or re-source. Without that link, even a detailed report can remain operationally weak.
A four-step decision model
- Confirm test relevance to service conditions and variant mix
- Identify the dominant metric: threshold, stiffness loss, or crack location
- Check repeatability across samples, builds, or suppliers
- Translate the result into design change, inspection control, or sourcing action
In practice, this model supports faster validation gates and stronger procurement alignment. A supplier with slightly higher unit cost may still provide lower total risk if the chassis fatigue limit test shows later crack initiation, lower scatter, and better correlation to simulation. Conversely, a low-cost option with incomplete fatigue evidence can create disproportionate field exposure and slower launch readiness.
For organizations operating across automotive, industrial mobility, precision tooling, and sustainability-driven equipment platforms, the broader lesson is consistency. Durability validation must be interpretable across functions, from engineering to sourcing to quality. GIM’s cross-sector benchmarking perspective is valuable here because the same structural questions often recur across different hardware categories: where does damage start, what margin exists, and how repeatable is the production outcome?
A chassis fatigue limit test becomes far more useful when it is treated as a structured source of engineering intelligence rather than a final checkbox. When technical evaluators focus on threshold load, crack initiation, stiffness evolution, failure location, and production relevance, they gain a clearer basis for platform validation, supplier comparison, and lifecycle risk control. If you need deeper benchmarking support, tailored evaluation criteria, or cross-industry guidance for structural durability decisions, contact GIM to get a customized solution and explore more technical validation insights.
The Archive Newsletter
Critical industrial intelligence delivered every Tuesday. Peer-reviewed summaries of the week's most impactful logistics and market shifts.