Monday, May 22, 2024
When Engine Components Fail Early, the Root Cause Is Often Upstream
by
Published
Views:
When engine components fail ahead of schedule, the issue often starts far upstream—in materials, circuit components, supplier controls, or system integration. Across EV Tech, smart transportation, Agri-Tech, and climate technology, advanced systems rely on hardware components that perform consistently under pressure. For evaluators, operators, and decision-makers alike, tracing these hidden causes is essential to building a resilient supply chain and reducing costly risk.
In modern manufacturing, early engine component failure is rarely an isolated mechanical event. It is often the visible outcome of hidden variation introduced 2, 3, or even 5 tiers earlier in the supply chain. A bearing that spalls at 800 hours instead of 3,000 hours, a control board that degrades after 200 thermal cycles, or a seal that hardens prematurely may all point to upstream weaknesses rather than downstream misuse alone.
For procurement teams, quality managers, engineers, project leaders, and financial approvers, this matters because the cost of failure expands far beyond the failed part itself. Warranty exposure, line stoppage, service dispatch, safety review, and delayed field deployment can multiply direct replacement cost by 3x to 10x. In cross-sector environments, the smartest response is not only replacing the failed component, but also benchmarking the upstream chain that produced it.
Why Early Failure Usually Starts Upstream
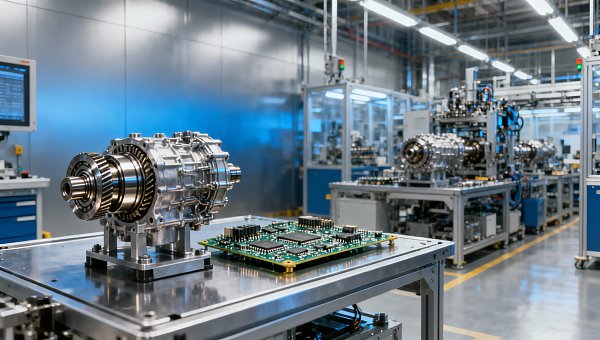
Engine systems now operate inside more integrated environments than they did a decade ago. In EV auxiliaries, hybrid drivetrains, smart agricultural equipment, and environmental infrastructure, the engine or engine-adjacent system is affected by electronics, firmware logic, thermal management, and supplier process stability. A problem may begin with raw material inconsistency at ±8% hardness variance, poor PCB solder reliability, or undocumented changes in sub-tier sourcing.
Upstream causes often stay hidden because incoming inspection typically focuses on visible dimensions and basic pass/fail checks. However, many failure mechanisms emerge only after 500 to 1,500 operating hours, 50 to 300 thermal cycles, or repeated vibration exposure in the 10 Hz to 2,000 Hz range. By the time symptoms appear in the field, root-cause evidence is already diluted across multiple suppliers and assembly steps.
This is especially true when buyers evaluate components in silos. A gasket may meet dimensional tolerance, but fail because the neighboring housing surface finish exceeds Ra recommendations. A sensor may pass electrical inspection, yet drift under moisture ingress because connector plating thickness was reduced during a cost-down revision. Early failure is often a systems problem disguised as a part problem.
Common upstream triggers behind premature failure
Across industrial sectors, four upstream triggers appear repeatedly: uncontrolled material substitutions, weak process capability, incomplete validation under real duty cycles, and fragmented supplier communication. If any one of these is missed during sourcing or qualification, component life can drop sharply even when initial samples look acceptable.
- Material drift: alloy grade, elastomer formulation, plating thickness, or resin content changes that stay within loose commercial ranges but outside actual application needs.
- Process instability: heat treatment variation, torque inconsistency, solder voiding, contamination, or curing time deviation across different production lots.
- Validation gaps: testing only for nominal load instead of peak load, vibration, dust, humidity, corrosion, or stop-start cycles.
- Integration mismatch: component-level compliance without verifying interaction with adjacent modules, controls, or enclosure conditions.
For organizations working across automotive, electronics, agriculture, and infrastructure, a cross-disciplinary benchmarking approach is essential. This is where a platform such as GIM becomes useful: not to treat each failure as a single-sector event, but to compare materials, hardware architectures, supplier controls, and standards alignment across the wider industrial stack.
Failure Modes That Cross Mechanical, Electrical, and Environmental Boundaries
Many early engine component failures are rooted in interactions between domains. Mechanical engineers may focus on fatigue, wear, and lubrication. Electronics teams may focus on voltage stability and connector integrity. ESG and infrastructure teams may look at moisture, chemical exposure, and service intervals. In reality, these factors overlap, and failure often occurs where disciplines meet.
Consider a smart mobility platform using electronically controlled actuation near an engine compartment or thermal source. If a board-level component is specified for 85°C continuous exposure but the actual localized temperature reaches 105°C during peak duty, solder fatigue, sensor drift, and connector embrittlement may accelerate. The failed module may be replaced several times before anyone traces the problem back to thermal mapping and enclosure design.
In Agri-Tech, equipment often runs through dust, moisture, vibration, and seasonal storage cycles. A component that performs well in a clean factory test for 100 hours may fail in the field after exposure to fertilizer residue, washdown practices, and intermittent cold starts. The upstream issue may not be poor product design alone, but incomplete scenario validation and inappropriate sealing material selection.
Typical cross-domain failure patterns
The table below summarizes common patterns that technical evaluators and procurement teams should examine when early failure appears before the expected service interval.
The key takeaway is that failure analysis should not stop at the broken component. It should extend to upstream material selection, process control windows, and adjacent system behavior. This broader view is particularly valuable for organizations comparing suppliers across multiple industrial sectors and international standards frameworks.
Where benchmarking adds value
Benchmarking becomes practical when teams compare parts against expected duty cycles, not just catalog specifications. For instance, ISO, IATF, and IPC alignment can help assess whether the supplier’s control plan, traceability discipline, and electronics assembly process are mature enough for the intended application. That approach reduces the chance of approving a low-cost part that generates high downstream risk.
How Procurement and Engineering Should Evaluate Upstream Risk
A strong sourcing decision should combine commercial review with technical validation. Too often, procurement compares unit price, quoted lead time, and minimum order quantity while engineering evaluates isolated performance data. Early component failure becomes more likely when these workstreams stay separate. In higher-risk categories, upstream risk should be reviewed through at least 4 lenses: material control, process capability, standards alignment, and integration evidence.
For example, a supplier offering a 12% lower component price may still create a higher total cost if process variation causes an extra 1% failure rate in the field. On a fleet of 5,000 units, even a small defect escape can trigger logistics costs, labor time, and customer dissatisfaction far beyond the initial savings. Technical and business evaluators therefore need a shared decision framework.
Core evaluation criteria before approval
Before final supplier nomination, teams should request evidence that goes beyond samples and datasheets. The checklist below is useful across automotive, electronics, smart equipment, and infrastructure-linked applications.
- Confirm material consistency across at least 3 production lots, not only prototype batches.
- Review process control metrics such as repeatability, critical dimensions, and test coverage at key manufacturing steps.
- Check whether environmental validation reflects real operating conditions, including humidity, dust, washdown, and thermal swing.
- Assess traceability depth for sub-tier materials, electronics, and assemblies that could affect field reliability.
- Verify change-control discipline, especially for alternate materials, firmware updates, and outsourced production transfers.
The following comparison table can support supplier reviews and internal approval discussions, especially when finance, quality, and engineering teams need a common language for risk.
This comparison shows why early failure prevention is not purely a quality function. It is also a sourcing, budgeting, and project governance issue. GIM’s cross-sector benchmarking model can help organizations compare suppliers and technologies using a broader, more defensible decision matrix.
A practical 3-stage approval model
A practical model includes 3 stages: desk review, pilot validation, and monitored scale-up. Stage 1 screens documentation and standards alignment. Stage 2 tests real application conditions over a defined period such as 2 to 6 weeks. Stage 3 tracks early production performance for the first 90 to 180 days. This staged approach lowers the probability of hidden upstream issues entering full production unnoticed.
Building a Root-Cause Workflow That Works Across Industries
When a component fails early, speed matters, but speed without structure often leads to superficial fixes. Replacing a part, tightening an assembly torque, or issuing a temporary containment action may stabilize the symptom for a few weeks. However, unless the workflow reaches the upstream source, the same failure can return in the next batch, next season, or next vehicle platform.
A reliable root-cause process should connect field data, lab findings, supplier records, and system-level operating conditions. In practice, that means looking at failure onset time, duty profile, lot history, maintenance pattern, environmental exposure, and design margins together. For many teams, the challenge is not the lack of data, but the lack of a cross-functional method to interpret it.
Recommended investigation sequence
The following 5-step sequence is widely applicable across engine systems, electrified auxiliaries, agricultural machines, and industrial infrastructure equipment.
- Contain the issue by isolating affected lots, operating conditions, or product families within the first 24 to 72 hours.
- Verify the failure mode through teardown, microscopy, electrical checks, and operating history review rather than relying on surface symptoms.
- Map the upstream chain, including raw material source, sub-tier electronics, process revisions, and tooling changes within the last 3 to 12 months.
- Recreate the condition using real duty cycles, such as thermal cycling, vibration, load peaks, moisture ingress, or contaminant exposure.
- Implement corrective action with measurable verification windows, for example 30-day containment and 90-day stability review.
The most common mistake is stopping at the nearest detectable cause. If a connector fails, teams may switch connector suppliers. But if the real issue is enclosure condensation or poor cable routing, the replacement will eventually fail too. Effective root-cause work always tests the system around the failed part, not just the part itself.
What different stakeholders should monitor
Operators should log the precise usage condition before failure. Quality teams should compare lot-level evidence and incoming inspection gaps. Engineers should verify design margins and environmental assumptions. Commercial teams should assess supplier change notices, capacity shifts, and cost-down activity. Decision-makers should then align corrective actions with long-term supply resilience rather than only short-term recovery.
This integrated model is increasingly important in sectors where electronics, mobility, sustainability, and infrastructure overlap. GIM supports this need by organizing technical benchmarking in a way that helps teams identify whether the real risk sits in material quality, process drift, component architecture, or systems integration.
FAQ: Selection, Lead Time, and Risk Control Questions Buyers Commonly Ask
Many organizations investigating early engine component failure are not only trying to solve a current issue. They are also trying to improve future sourcing decisions. The questions below reflect common search intent from engineering teams, procurement managers, quality leaders, and industrial strategists.
How should buyers compare component suppliers when failure risk is hard to see?
Start with four categories: technical fit, validation depth, process transparency, and change-control discipline. Do not rely only on price, catalog performance, or a single successful sample run. A supplier with slightly longer lead time of 4 to 8 weeks may still be lower risk than one shipping in 2 weeks if the former can document stronger process controls and traceability.
What lead time is realistic for deeper verification before approval?
For many industrial components, a basic desk review can be completed in 5 to 10 business days. Pilot testing may require 2 to 6 weeks depending on environmental conditions and duty-cycle complexity. If a component is safety-critical or exposed to harsh operating conditions, a 60- to 90-day monitored validation window is often more defensible than rushing to full deployment.
Which indicators suggest the root cause is upstream rather than operator misuse?
Look for repeated failure within the same lot, similar failure signatures across locations, drift after process changes, or issues emerging shortly after a supplier transfer. If failures cluster around 200 to 500 operating hours regardless of operator profile, the pattern often points to material, assembly, or design integration problems rather than usage alone.
How can distributors and project leaders reduce field risk before scale-up?
Distributors should request application-specific validation data, not just generic product sheets. Project leaders should define acceptance criteria early, including environmental thresholds, cycle counts, and documentation requirements. A controlled rollout in 2 or 3 phases is usually safer than a single-volume launch, especially for new suppliers or mixed mechanical-electronic assemblies.
From Hidden Failure to Better Supply Chain Decisions
When engine components fail early, the real lesson is not simply that a part broke. The lesson is that the upstream system may be underqualified, under-monitored, or poorly integrated. Whether the issue appears in EV platforms, intelligent transport, precision agriculture, or environmental infrastructure, resilient performance depends on better transparency across materials, electronics, processes, and standards alignment.
Organizations that investigate failures through a cross-sector lens are better positioned to reduce warranty exposure, improve sourcing confidence, and make more durable investment decisions. That means combining mechanical analysis with electronics benchmarking, supplier governance, and application-level validation instead of treating each problem as an isolated defect.
Global Industrial Matrix helps procurement teams, engineers, quality leaders, and executive decision-makers compare upstream risk with greater clarity across Semiconductor & Electronics, Automotive & Mobility, Smart Agri-Tech, Industrial ESG & Infrastructure, and Precision Tooling. If you need a more structured way to evaluate failure risk, benchmark suppliers, or build a stronger technical sourcing strategy, contact us to explore a tailored solution and learn more about cross-sector benchmarking support.
- electronics
- advanced systems
- circuit components
- Mobility
- EV Tech
- Smart Transportation
- engine components
- smart transportation
- Agri-Tech
- precision agriculture
- Industrial ESG
- climate technology
- hardware components
- Precision tooling
- Technical benchmarking
- Smart Agri-Tech
- Resilient supply chain
- Modern manufacturing
- Industrial strategists
- Industrial infrastructure
- Environmental infrastructure
The Archive Newsletter
Critical industrial intelligence delivered every Tuesday. Peer-reviewed summaries of the week's most impactful logistics and market shifts.